Introduction
I build kotonia on my own. Its center is character chat, but it also has a "workspace" for groups, and inside that, shared tables that work like a simple spreadsheet.
The day I added CSV import to the shared tables, I asked my wife to try it: move the baby log she keeps every day out of the app she uses now.
The app had an export. What came out was text like this (names and numbers made up; the app is Japanese):
----------
2026/1/5(月)
〇〇ちゃん (0か月10日)

00:30   ミルク 40ml
12:50   母乳 左 15分
13:00   母乳 左 2分 / 右 6分
02:25   うんち   多かった(二日ぶり)
10:55   くすり   K2

母乳合計     左 17分 / 右 6分
ミルク合計    1回 40ml
(ミルク = formula, 母乳 = breastfeeding with 左/右 = left/right minutes, うんち = poop, くすり = medicine; the last two lines are the day's totals.)
As a format for sending to another person, it is well made. It is not a table, though. The date only appears in a heading, one line holds two values, and daily totals are mixed in with the records. Paste it into a spreadsheet and it all lands in one column.
My wife had asked a different AI to turn it into a CSV and then imported that. It worked, but I can't ask every user to do that each time.
An export that does not produce something usable leaves the data effectively locked inside the app. That is not someone else's problem. I hold people's data too.
This post covers what I built in the two days around that. There are two themes:
- Letting people bring data in, take it out, and look at it their own way (more choices)
- Using AI to remove as much of the hassle of doing that as possible (less friction)
I used AI freely. In exchange, I drew a line: wherever data could be corrupted or leave the system, the service takes responsibility, not the AI. I'll say where I drew it.
The choices
Taking data out: export
Shared tables export to CSV and JSON.
- CSV is for spreadsheets. It carries a BOM so Excel does not garble the characters, writes date-times in the viewer's local time, and member columns as names
- JSON is for other tools. It has the raw values (date-times in UTC, members as IDs) and the table's structure
An exported CSV can be imported again as is. When the headers match the column names, the columns line up without calling the AI. If the way out and the way in do not fit together, export is a one-way door.
Bringing data in: import
CSV and TSV files, cells pasted from a spreadsheet, and text that is not a table. It also reads Shift_JIS CSVs from Japanese Excel.
Looking at it your own way: custom views
You can turn a table into the dashboard you want. Without writing HTML, you type "monthly formula amounts as a bar chart" or paste a design image, and the AI writes the view.
What I handed to the AI
All of these are tedious by hand, and a mistake in them can be fixed later.
| Task | What the AI does | Time (measured) |
|---|---|---|
| Column mapping | Which file column goes to which table column | not measured |
| Designing a new table | Proposes column names and kinds (number, date, choice…) | 7–12 s |
| Values the rules can't read | ミルク (half-width katakana) → the choice "ミルク", etc. | 3–5 s |
| Text that isn't a table | Writes how to read the lines (patterns) | 15–32 s |
| Custom views | Writes the HTML (about 7 s to just fix one) | 33–60 s |
The AI is a local LLM on GPUs in my home, and none of the data sent to it leaves for an outside service. For this feature that was a premise, not an option. I don't want people to decide, every time, whether their baby log or household budget may go to another company's API.
The adventure: getting all 135 records back
"Reading CSV is enough" broke on the first real file
I built import for CSV first. Values (full-width digits, units like 120ml, 2026年11月16日, 午後3時 = 3 p.m., ○ or 済 for yes) are read by fixed rules in code; the AI only says "this column is that column." The messy CSV I made for testing went through fine.
Then the first real data was the text above. Not even a table. From here on is how I got my wife's file in as is (in my development environment; the data never left my machine).
Having the AI write how to read it
I could have had the AI convert it line by line. But a month is hundreds of lines; it would be slow, and there would be no way to trace what changed where.
Instead, the AI sees the start of the text and writes only how to read it: line patterns, as regular expressions with named groups. "Lines shaped like this are a date heading." "Lines shaped like this are records, with the time, kind and amount here." "Skip the totals." Applying the patterns to every line is the code's job.
Since an AI writes the regexes, I run them on a regex engine that does not backtrack (Rust's regex) with a size cap, so an odd pattern cannot hang the server.
First try: 124 / 135
The right answer is 135 records (formula 102, breastfeeding 25, poop 5, medicine 2, spit-up 1). The first try read 124. And they were missing things:
- No time column. The pattern matched the lines but had no group capturing the time
- No kind column. It wrote one pattern per kind of line, with "ミルク" as fixed text inside the pattern, never captured as a value
- Empty dates. This one was my bug. I cleared every carried value whenever a heading was read, so the "〇〇ちゃん" line right under the date heading wiped the date
Every fix was a general check. I added no rule for any particular app.
- Headings form a hierarchy from outer to inner (a date clears the name under it; a name keeps the date above it)
- If a digit on a record line ended up in no group, the AI gets that line back as "you are dropping a value"
- When there are several record patterns, each must capture the kind as a value
- A column that never gets a value is sent back too
The lines past line 80
Even with those checks, it sometimes passed with 11 lines unread. The reason was simple: the first 80 lines the AI sees had no "medicine" lines and no two-sided feedings. Rare kinds of lines only show up later in the file.
Applying patterns is mechanical and cheap, so the evaluation runs on the whole file. The AI sees only the start, but the lines it failed on, including later ones, go back to it concretely, for up to four rewrites. Now three runs out of three read all 135.
The same shape of problem showed up in table design. When the AI proposed a choice column, it only knew "formula, breastfeeding, poop" from the first 30 rows, and the later "medicine" could not be imported. Choices are now filled in from the whole file.
What the AI can be shown is limited. What you can check is not. That was the idea that helped most this time.
The count was right, and the values were broken
135 records in, zero errors. I nearly stopped there. But the table the AI proposed had only one "feeding minutes" column. How had the two-sided feedings gone in? I looked at the database directly.
左 2分 / 右 6分 (left 2 / right 6) was stored as 26 minutes, 左 15分 / 右 3分 as 153, 左 10分 / 右 10分 as 1010.
Two causes stacked:
- In the table design, the AI put left and right minutes into one number column, so the value arrived joined, like
2 6 - My number reader, trying to handle thousands separated by spaces like
1 200, removed all spaces and commas before looking for a number.2 6silently became 26. For the same reason2,5became 25
Either one alone would not have caused damage. Together, they broke values without a single error.
The fix: when something can be read two ways, don't decide silently. A comma counts as a thousands separator only when exactly three digits follow it. Anything else, like 2 6 or 2,5, is listed before import as "several numbers." Table design no longer joins several columns into one, except a date with a time.
After the fix I checked values, not counts. The file has daily totals (lines the import skips). I compared those with the totals of what was imported.
| File's totals | Imported values | |
|---|---|---|
| Formula | 11,650 ml | 11,650 ml |
| Breastfeeding, left | 277 min | 277 min |
| Breastfeeding, right | 49 min | 49 min |
| Count (formula / breast / poop / medicine / spit-up) | 102 / 25 / 5 / 2 / 1 | 102 / 25 / 5 / 2 / 1 |
The count and "0 errors" said almost nothing about correctness. I caught this because something looked off and I went looking, which is close to luck. To check, compare against the answers the source data already holds (here, its own totals).
What the service takes on
Because I handed a lot to the AI, the places where data could be corrupted, leak, or become unrecoverable are held by code, not left to the AI's judgment.
Always a preview before writing. Import shows how many rows will go in and which values could not be read before it writes anything. If some rows cannot be read, you have to choose "skip them" explicitly.
Imports can be undone. Each import is one transaction, and its rows are marked. "Undo this import" removes only rows nobody has edited since.
Nothing unreadable is hidden. A value in the wrong unit (左5分, five minutes, arriving in a millilitre column) and lines that match no pattern are listed, not dropped or rounded. You can fix them by hand, have the AI fix them, or leave them empty.
The AI does not rewrite values. What it produces are mappings, readings and reading rules; applying them to every row and the final type checks are done by code, the same checks as typing a row by hand.
Custom views are read-only. The HTML the AI writes runs in an isolated frame with no login (a sandboxed iframe). It can only ask the parent page for data, and the parent relays reads and nothing else. There is no way to write, by construction rather than by request.
There is one hole I can't close. The page inside the frame can navigate itself to another URL. When I tried it, the request to the new address did go out (the view is stopped right after). I accept this because a view can only read the group's shared data, and whoever made the view can already read all of it. So nothing that differs per viewer goes into that relay. The moment it does, this hole becomes a real leak.
Closing
Two days ago, my wife's records were text inside an app, meant for sending to someone. Now that text goes into a shared table with no preprocessing.
From those records I also built a "one day at a time" timeline as a custom view. Switch the date and that day's records and totals line up.
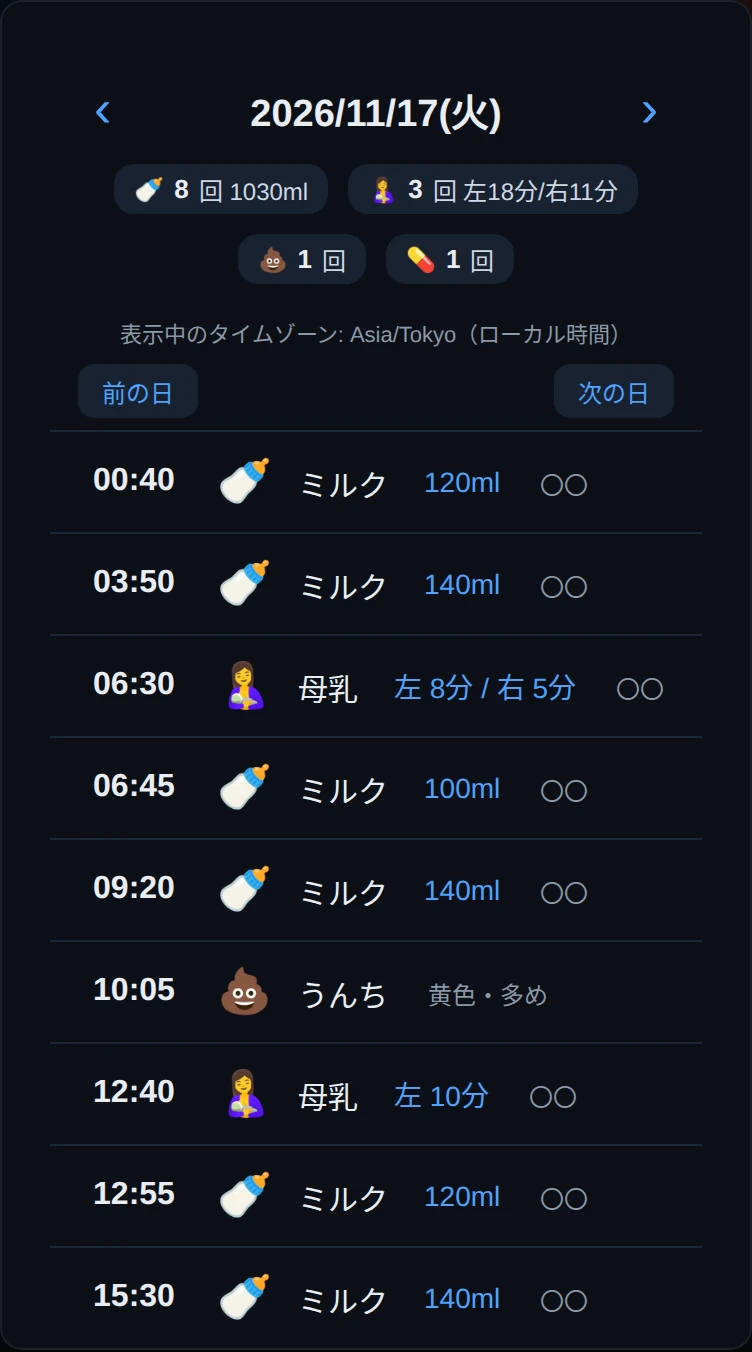
What I took away is that whether people can take their data with them is not decided by an export button. It is decided by whether what comes out can be used in the next place. That always involves tedious conversion, and that tedium is exactly where AI helps most. But the more of it the AI takes on, the more ways a value can change without anyone noticing. So that risk is the service's to carry.
Shared tables and custom views are part of kotonia's group features. A monthly plan (from ¥500) or a prepaid top-up gives you your own group, and you can invite family or others with a kotonia account to use it together.